Our first-hand build of a bilingual Home Assistant local voice assistant: what runs on the box, what we sent to the cloud, what broke, what it costs, and why microphones are the real obstacle.

LLM integration
Self-Hosted LLM on Your Own GPU Box: What It Really Takes
Running a self-hosted LLM takes a correctly sized GPU, an efficient inference server and an operational layer for auth, monitoring, updates and fallback, and that last part decides whether it survives.
GPT-6.2 Astra and Fable 5.5 leak in the same week: plan your eval
OpenAI and Anthropic both appear to be days from shipping new flagships, so the useful move this week is a ready evaluation harness, not a leaderboard refresh.
Dataflow Security in AI Pipelines: Map, Restrict, Audit
Most AI data leaks happen in the plumbing around the model, so dataflow security means mapping every hop, restricting each one and auditing until the map stays true.
Self-Hosted LLM vs API: Cost, Latency and GDPR Trade-offs
For most businesses an LLM API wins on cost and speed to ship, and self-hosting an open-weight model only pays off with high steady volume, strict data control or tight latency needs.
RAG vs Fine-Tuning: Which Does Your Use Case Actually Need?
For most businesses the answer is retrieval first: RAG fixes what a model doesn’t know, fine-tuning changes how it behaves, and plenty of use cases need neither.
AI Invoice Processing Automation: A Worked Example
A step-by-step worked example of AI invoice processing automation, from the AP inbox to a draft bill, showing where the LLM fits, where plain code must take over and where a human still decides.
LangGraph vs CrewAI vs Custom: Choosing an Agent Framework
Choose LangGraph for explicit state and control, CrewAI for fast role-based prototypes, and custom code when your agent is one model calling a few tools, but draw the workflow before you pick any of them.
Replit reportedly drops Anthropic for OpenAI over a 30% price cut
A deeply integrated, Claude-built company reportedly switched frontier providers for a 30%-plus discount, which makes every model contract a renegotiation waiting to happen.
Home Assistant Local Voice Assistant: Bilingual for $2 a Month
How we built a mostly local English and Polish voice assistant on Home Assistant with Whisper, Piper and a small hosted LLM, what broke along the way, and why it costs about $2 a month.
Black October: PHP2Shell, LiteLLM 1.107.0 and what to patch now
Two actions matter after Black October: get PHP onto the 21 October fixes, and treat any machine that installed LiteLLM 1.107.0 as compromised.
How Much Does It Cost to Build an AI Agent in 2026?
A practical breakdown of what a custom AI agent costs to build and run in 2026, tier by tier, with the cost drivers that actually move the number.
LLM Integration: A Complete Guide for Production Systems
LLM integration is mostly about the layers around the model: a gateway, context assembly, validation, evaluation, observability and guardrails. This guide covers how to build each one for production.
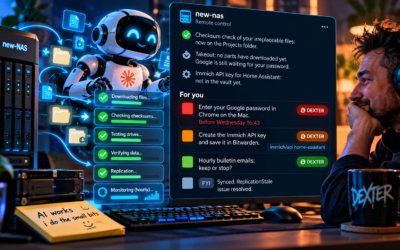
Human-in-the-Loop Action Tags: How to Make AI Agents Easy to Steer from Your Phone
A simple pattern for running AI agents from your phone: four coloured action tags, one task per line and a closing ‘For you’ list, so the human in the loop never misses an ask.
Integrating Large Language Models (LLMs) into Legacy Enterprise Systems
Put a thin, tested façade in front of the legacy system, decouple model calls with queues, retrieve rather than retrain, and keep people on the consequential writes.
What We Do
Product
Consumer and enterprise software, built with taste and shipped fast.
Infrastructure
AI agents, automation, and orchestration - production systems, not demos.
Advisory
Hands-on engineering and strategy for teams shipping AI into production.